Second-Moment Trust Policy Optimization (M2PO)#
Last updated: Oct 23, 2025
Author: Jingyuan Ma
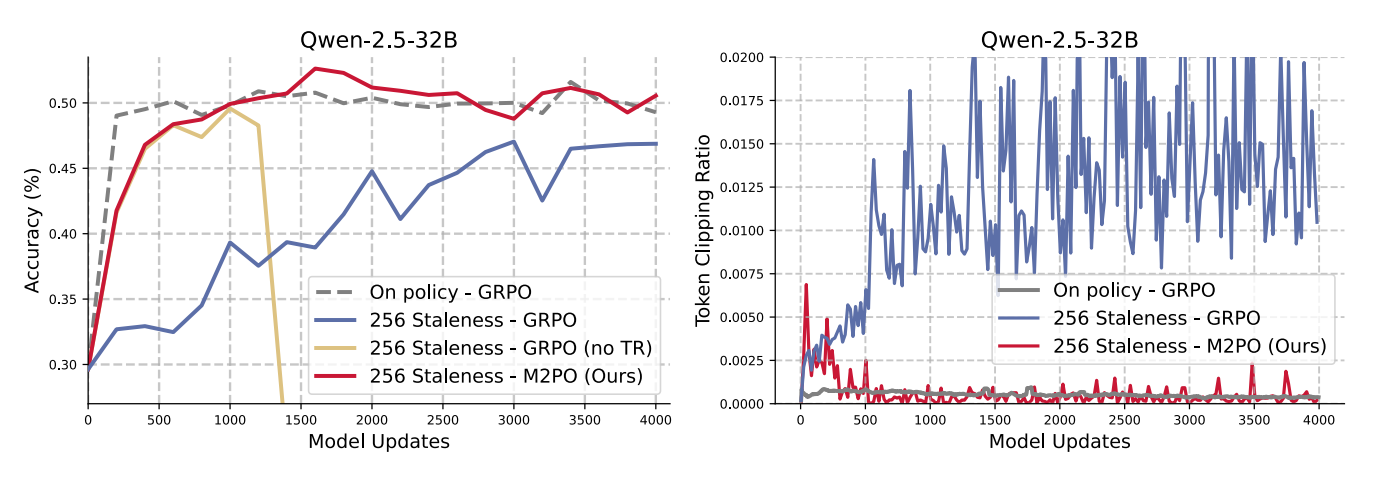
Second-Moment Trust Policy Optimization (M2PO) (Zheng et al., 2025) is an RL method that achieves stable off-policy training even when data is stale by at least 256 model updates and matches on-policy performance by constraining the second moment of importance weights to suppress only extreme outliers while preserving informative updates.
The first step of M2PO is to compute the second moment: $\( \hat{M_2}=\frac{1}{N}\sum_{i=1}^NM_{2,i}=\frac{1}{N}\sum_{i=1}^N(\log{r_i})^2=\frac{1}{N}\sum_{i=1}^N\left(\log\frac{\pi_\theta (a_i|s_i)}{\pi_{behav}(a_i|s_i)}\right)^2 \)$
The second step is to compute the second-moment mask:
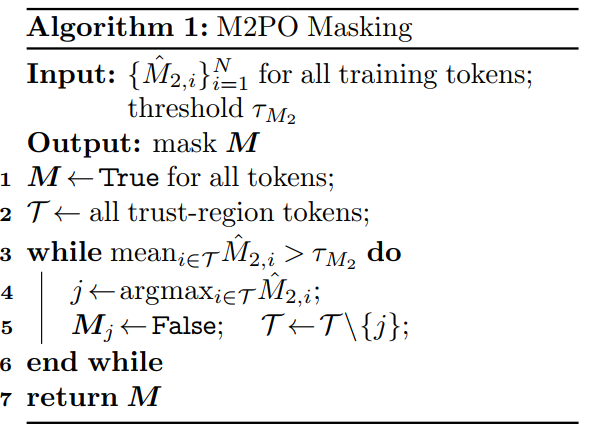
The final step is to optimize the objective:
Where \(M\) is computed in the second step and
For more details:
AReaL details: AReaL paper
M2PO details: M2PO paper
Core Parameters#
actor.m2_threshold: The threshold for the mean of the second moment, used in computing the M2PO mask as \(\tau_{M_2}\)
Example Usage#
We recommend changing the parameters in the configuration file
(examples/math/gsm8k_m2po.yaml).
Backend |
CMD |
|---|---|
local |
|
ray |
|
slurm |
|
Test Result#
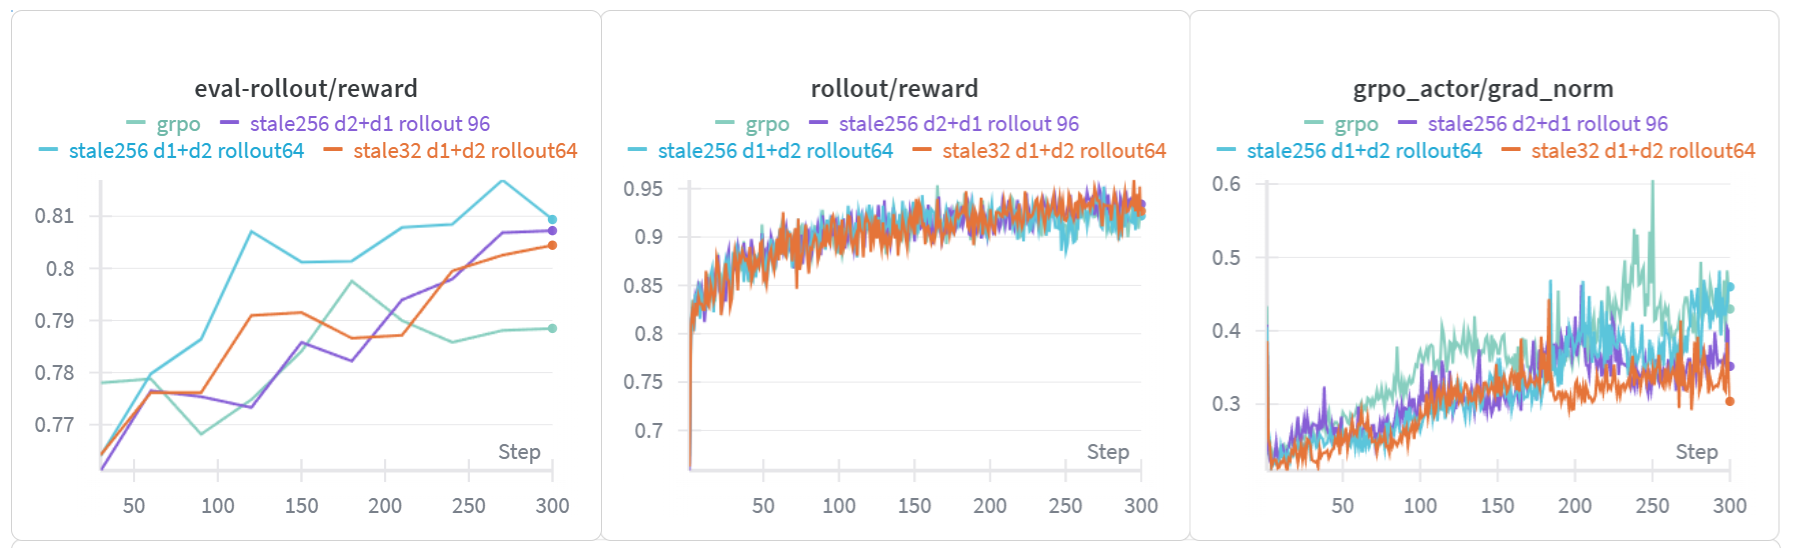
In this test, trial names follow these conventions:
stale: the value of
max_head_offpolicynessdx+dy:
xis the number of rollout workers andyis the number of training workersrollout: the value of
max_concurrent_rollout
The GRPO setting is stale 256 d2+d1 rollout 96.
The key findings across the trials are as follows:
The
grad_normof GRPO is higher than M2PO, which may cause training instability.The evaluation reward of M2PO is higher than GRPO.